Skip to content

Iqraa.tech

Hands-on tutorials for Claude Code, AI agents, cloud and system design

  • AI & GenAI
    • Claude
    • OpenAI
    • AI Agents
      • Learning Hub
      • AI Agent Resources
    • LLM Inference
    • AI Tools & Workflows
  • AWS & Cloud
  • Creator Picks
  • System Design
  • Technical Architect
    • AI & ML Fundamentals
    • Cloud Computing
    • DevOps Fundamentals
    • Docker
  • DevOps Prep

Posts Tagged → inference

How ChatGPT Works: KV-Cache, GPU Cluster, and the Router

posted in System Design on July 26, 2026 by Amar Tinawi
How ChatGPT works architecture diagram with GPU cluster and KV-cache

A look at how ChatGPT works. ChatGPT served 100 million weekly active users within two months of launch, the fastest consumer-software adoption in history. The architecture that scaled to that size wasn’t new technology; it was the careful application of patterns every ML inference system has used for years, plus one trick: the per-session KV-cache… Continue reading →

GPT-5.6 on Amazon Bedrock: Inference, Pricing, and Quotas

posted in AWS & Cloud on August 24, 2026 by Amar Tinawi
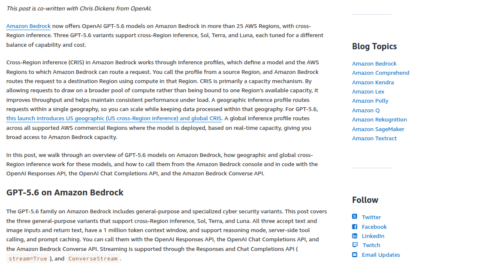
GPT-5.6 on Amazon Bedrock announcement on the AWS Machine Learning Blog

GPT-5.6 now runs on Amazon Bedrock. OpenAI’s current frontier family is available in more than 25 AWS Regions, reachable through cross-region inference profiles. This guide shows you how to enable the models, call them three different ways, read the real price sheet, and size quotas without surprises. GPT-5.6: What You’ll Learn GPT-5.6 arrived on Amazon… Continue reading →

Bedrock Prompt Caching: the Cost and Latency Math

posted in AWS & Cloud on September 20, 2026 by
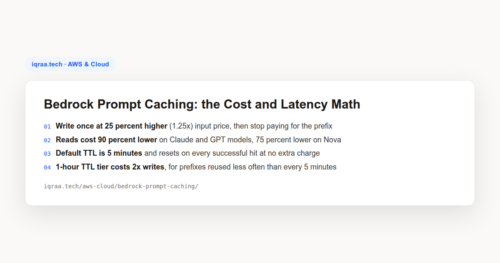
Original summary card for the Bedrock prompt caching tutorial: write at 1.25x input price once, reads 90 percent lower on Claude and GPT models, default 5 minute TTL, 1 hour tier at 2x writes.

TL;DR 30 sec8 min coredeep dive optional Prompt caching on Amazon Bedrock charges 25 percent more to write a cached prefix and 90 percent less to read it back, so any context you reuse within the TTL bills at a fraction of the standard input rate. Cache reads cost 90 percent less than standard input… Continue reading →

Tiny-LLM: Build a Mini vLLM on Apple Silicon

posted in LLM Inference on September 24, 2026 by
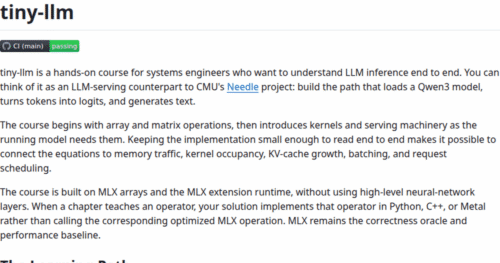
Tiny-LLM course repository on GitHub describing the four week path from matrix multiplication to a mini vLLM serving engine

TL;DR 30 sec7 min coredeep dive optional Tiny-LLM is a hands-on course where you build an LLM serving engine from raw array operations on Apple Silicon: KV cache, continuous batching, and paged attention, ending with a coding agent running on the engine you wrote. Four weeks: Qwen3 from matrix multiplies, a faster single request, a… Continue reading →

Zero to SGLang: the Official Inference Course

posted in LLM Inference on September 24, 2026 by
Zero to SGLang official course README on GitHub showing the syllabus table from first server deployment to mini SGLang construction chapters

TL;DR 30 sec7 min coredeep dive optional Zero to SGLang is the official SGLang course, built with the Datawhale community, that takes you from running your first inference server to building a mini SGLang engine and then into the real one’s advanced internals. Part 0 gets a Qwen3-0.6B server running on your GPU in the… Continue reading →

Mooncake Explained: KV-Cache-Centric LLM Serving

posted in LLM Inference on September 24, 2026 by
Mooncake repository on GitHub describing the KVCache-centric disaggregated architecture with Transfer Engine benchmark figures

TL;DR 30 sec6 min coredeep dive optional Mooncake is Moonshot AI’s open-source serving architecture that treats the KV cache as the center of the system: prefill and decode run on separate clusters, and a disaggregated cache pool built from spare CPU, DRAM, and SSD moves context at RDMA speed. Best Paper at FAST 2025, and… Continue reading →

How Cloudflare Cut Its Inference Cost by 68%

posted in LLM Inference on October 20, 2026 by
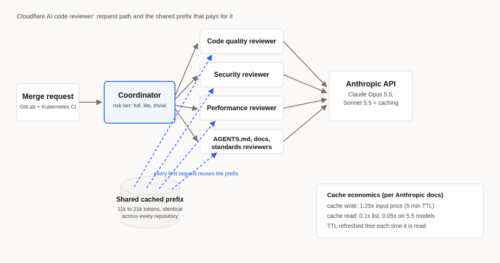
Diagram of the Cloudflare AI code review pipeline that drove inference cost down 68 percent: a merge request reaches a coordinator that risk tiers it to specialist reviewers, and every reviewer first request reuses one shared cached prefix before hitting the Anthropic API

TL;DR 30 sec6 min coredeep dive optional Cloudflare cut the inference cost of AI code review from $2.43 to $0.77 per review by moving one prompt cache breakpoint, deleting model calls nobody needed, and stepping models and effort down only where quality held. The cache fix alone lifted first-request cache hit rates from 14 to… Continue reading →

Recent Posts

  • Claude Code SEO Audits: Find What Crawlers Miss in 2026
  • Loop Engineering: The 3 Layers of Agent Architecture
  • Claude Gates: Make Claude Code Prove Its Work in 2026
  • REA: Reverse Engineer Anything With Claude Code
  • How Cloudflare Cut Its Inference Cost by 68%

Recent Comments

No comments to show.
Iqraa.tech

Hands-on tutorials for Claude Code, AI agents, cloud and system design. Interactive labs, real code examples, and knowledge checks.

LinkedIn GitHub dev.to

Learn
  • Claude Code
  • OpenAI Academy
  • AI & GenAI
Resources
  • Claude Code Docs
  • OpenAI Docs
  • Search Tutorials
Iqraa.tech
  • Home
  • About
  • Contact
  • All Tutorials
  • RSS Feed
© 2026 Iqraa.tech · Tech Tutorials
Privacy Policy · Terms of Service
Built for Tech, with <3.

Analytics cookies

We use Google Analytics to see which tutorials are actually useful. Nothing is used for advertising or sold. You can change your mind any time. Privacy Policy