GPT-5.6 now runs on Amazon Bedrock. OpenAI’s current frontier family is available in more than 25 AWS Regions, reachable through cross-region inference profiles. This guide shows you how to enable the models, call them three different ways, read the real price sheet, and size quotas without surprises. GPT-5.6: What You’ll Learn GPT-5.6 arrived on Amazon… Continue reading
Posts Tagged → prompt caching
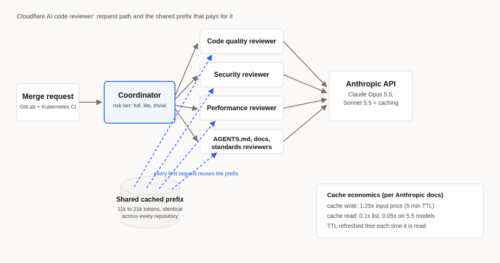
How Cloudflare Cut Its Inference Cost by 68%
TL;DR 30 sec6 min coredeep dive optional Cloudflare cut the inference cost of AI code review from $2.43 to $0.77 per review by moving one prompt cache breakpoint, deleting model calls nobody needed, and stepping models and effort down only where quality held. The cache fix alone lifted first-request cache hit rates from 14 to… Continue reading
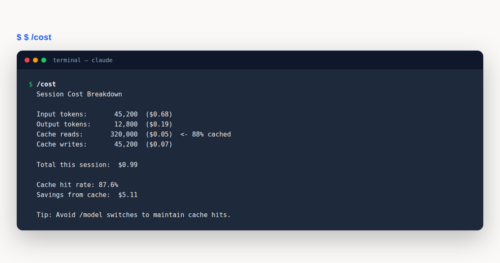
Claude Code Prompt Caching Explained
Prompt caching is the single biggest lever for cutting Claude Code costs on long sessions. It lets the API skip reprocessing your entire conversation history on every turn, billing you roughly one tenth the normal input rate for repeated prefixes. This guide covers how the cache is organized, the eight actions that invalidate it, the… Continue reading